Intro
I rebuilt my homelab Kubernetes cluster from scratch and wanted three simple things on top of it: Cilium L2 announcements, a LoadBalancer IP pool, and a Gateway API entry point for the APIs I plan to deploy later.
The LoadBalancer IP showed up, ARP resolved, and the Gateway reported Programmed: True. Yet every HTTP request from outside the cluster just hung.
The root cause turned out to be an interaction between three components that are each fine on their own: Cilium’s transparent proxy, Tailscale’s rp_filter workaround, and the Proxmox bridge firewall. This post covers the setup, the symptoms, the dead ends, and the one sysctl that fixed it.
TL;DR:
tailscaledsetsnet.ipv4.conf.all.src_valid_mark=1. With that set, the kernel drops the reply from the backend pod to Cilium’s Envoy as a martian packet. Setnet.ipv4.conf.eth0.accept_local=1on the nodes. Also, don’t use Cilium DSR mode behind the Proxmox VM firewall.
Update:
eth0alone is not enough. When the Gateway’s backend pod runs on the same node as the Envoy handling the request, the reply arrives on the pod’slxc*interface and is dropped as martian there too (found later with Headlamp:martian source 10.0.0.95 from 10.0.0.171, on dev lxc...). Setnet.ipv4.conf.all.accept_local=1as well. The fix section below includes it.
The Figure
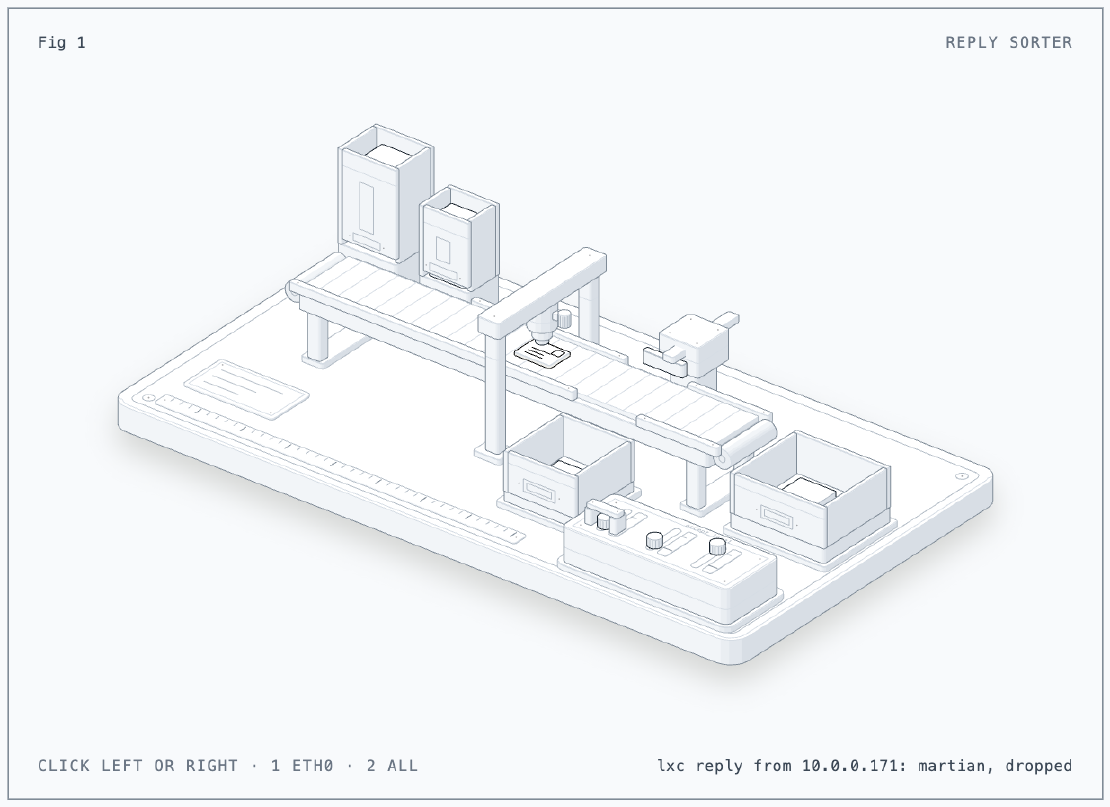
Each letter is a reply from the backend pod to Envoy. It comes in through one of two magazines: eth0 when the backend runs on another node, lxc when it runs on the same node. The reader head checks the return address the way the kernel does with src_valid_mark=1, so with the TPROXY mark the source looks local and the letter is pushed off into the reject bin as martian. The switch on the left is locked at 1 because tailscaled sets it again on every start. Click the left or right half of the figure, or press 1 or 2, to flip accept_local on eth0 or on all and see which replies reach the Envoy tray. With only eth0 set, the lxc replies still drop, which is the update above.
I generated the figure with the anatomy agent skill.
The Situation
Hardware and platform
- 3 Proxmox VE 9 nodes (
pve-01,pve-02,pve-03), VMs bridged onvmbr0with the Proxmox firewall enabled on each NIC. - 8 VMs built from a Debian 13 (trixie) cloud image with cloud-init:
- 3 k0s controllers, one per Proxmox node, with a keepalived VIP
192.168.101.151for the API. - 5 workers: 2 on
pve-01, 2 onpve-02, 1 onpve-03.
- 3 k0s controllers, one per Proxmox node, with a keepalived VIP
- k0s v1.36.4 installed with k0sctl, with
kube-proxydisabled and a custom CNI. - Tailscale on every VM for SSH access (Tailscale SSH), with
--accept-routesoff.
Cilium configuration
- Cilium 1.20.2, native routing with
autoDirectNodeRoutes, pod CIDRs10.0.x.0/24. kubeProxyReplacement: true.l2announcements.enabled: trueandgatewayAPI.enabled: true.- Gateway API CRDs v1.6.1. I matched the version to
sigs.k8s.io/gateway-apiin Cilium’sgo.modinstead of taking the latest release.
The objects I added:
apiVersion: cilium.io/v2
kind: CiliumLoadBalancerIPPool
metadata:
  name: lab-ip-pool
spec:
  blocks:
    - start: "192.168.101.152"
      stop: "192.168.101.168"
---
apiVersion: cilium.io/v2alpha1
kind: CiliumL2AnnouncementPolicy
metadata:
  name: l2-announcements
spec:
  interfaces:
    - ^eth[0-9]+
  externalIPs: true
  loadBalancerIPs: true
---
apiVersion: gateway.networking.k8s.io/v1
kind: Gateway
metadata:
  name: lab-gateway
  namespace: gateway
spec:
  gatewayClassName: cilium
  infrastructure:
    annotations:
      io.cilium/lb-ipam-ips: "192.168.101.152"
  listeners:
    - name: http
      protocol: HTTP
      port: 80
      allowedRoutes:
        namespaces:
          from: All
CiliumLoadBalancerIPPool is served as cilium.io/v2 now, and v2alpha1 is deprecated. CiliumL2AnnouncementPolicy is still only v2alpha1.
Issue 0: The Small Ones
Before the real problem, a few simpler mistakes got in the way.
The IP pool overlapped live addresses. My old pool was .150-.170. It contained the k0s API VIP (.151) and some other device on the LAN (.169). Cilium would have happily handed the API VIP to a LoadBalancer Service. A quick ping sweep plus the neighbor table on a Proxmox host found both:
for i in $(seq 150 170); do ping -c1 -W1 192.168.101.$i >/dev/null 2>&1 & done; wait
ip neigh show dev vmbr0
arping wasn’t installed, so the first sweep silently reported “nothing in use”, even for the VIP. Always sanity check a scan against an address you know is taken.
Another service took the Gateway’s IP. With ingressController.enabled: true, the cilium-ingress LoadBalancer Service grabbed .152 first, and the Gateway sat at <pending>:
The IP '192.168.101.152' is already allocated to another service
Fix: pin the ingress Service in the Helm values.
ingressController:
  enabled: true
  service:
    annotations:
      io.cilium/lb-ipam-ips: "192.168.101.153"
Issue 1: DSR Replies Dropped by the Proxmox Bridge
Symptom
ARP for .152 resolved to a worker’s MAC, so L2 announcements were working. But HTTP to .152 timed out from outside the cluster. A test NodePort Service showed the pattern:
| Node | NodePort result |
|---|---|
| Node running the backend pod | 200 |
| Every other node | timeout |
Pod-to-pod traffic across nodes, and even across Proxmox hosts, worked fine.
Cause
My old values had loadBalancer.mode: dsr. With Direct Server Return, the node that receives the request forwards it to the backend node, and the backend node replies directly to the client. The reply takes a different path from the request.
Each VM NIC has the Proxmox firewall enabled, so the host bridges it through a fwbr* bridge with net.bridge.bridge-nf-call-iptables=1. Host conntrack sees a SYN-ACK for a connection whose SYN it never saw, marks it INVALID, and the PVE firewall drops it.
Fix
Go back to the default SNAT mode by removing loadBalancer.mode from the values. After that, every NodePort answered from every client.
Issue 2: The Gateway Accepts, But Never Answers
This was the real one.
Symptom
Now Envoy accepted the TCP connection, but requests hung. Envoy’s admin socket showed the upstream to the backend pod failing:
A=/var/run/cilium/envoy/sockets/admin.sock
curl -s --unix-socket $A http://localhost/clusters | grep cx_connect_fail
# gateway/cilium-gateway-lab-gateway/nettest:echo:80::10.0.3.3:8080::cx_connect_fail::4
The upstream socket itself looked interesting:
ss -tneo state syn-sent | grep 8080
# 10.0.2.87:39741  10.0.3.3:8080  ... fwmark:0x80b00
10.0.2.87is the node’sreserved:ingressendpoint IP. Envoy uses it as a transparent source address for upstream connections.0x80b00is Cilium’s proxy-egress magic mark (0xb00) with the security identity in the upper bits. Identity8isreserved:ingress.
Dead ends
This is where I lost most of the time. Each of these was plausible, and each was wrong:
- Tailscale ip rules colliding with Cilium marks. Tailscale installs
fwmark 0x80000/0xff0000policy rules, and the ingress identity produces exactly0x80000in those bits. A perfect-looking collision. But stoppingtailscaled(which removes the rules;tailscale downdoes not) didn’t fix it. - XDP acceleration (
loadBalancer.acceleration: best-effort). Disabled it, no change. endpointRoutes. Disabled it, no change.- Interface naming. Previous attempts in this homelab had issues with interface name patterns, but the VMs use
eth0, and Cilium reportedDevices: eth0 (Direct Routing). - Restarting the operator, agents, and Envoy. No change. (It did surface a separate gotcha, covered below.)
Packet captures were also misleading early on. At one point the SYN seemed to vanish between netfilter and the wire. That turned out to be stale config, not the real failure.
Finding it: ask the kernel why it dropped the packet
What finally worked was skipping theories and asking the kernel directly. bpftrace on the kfree_skb tracepoint, filtered to the backend IP (10.0.3.3 is 0x0303000a in network byte order):
tracepoint:skb:kfree_skb {
  $skb = (struct sk_buff *)args->skbaddr;
  $ip = (struct iphdr *)($skb->head + $skb->network_header);
  if ($ip->daddr == 0x0303000a || $ip->saddr == 0x0303000a) {
    printf("drop reason=%d loc=%s src=%s dst=%s dev=%s mark=0x%x\n",
      args->reason, ksym(args->location), ntop($ip->saddr), ntop($ip->daddr),
      $skb->dev->name, $skb->mark);
  }
}
Output:
drop reason=2 loc=ip_rcv_finish_core.isra.0 src=10.0.3.3 dst=10.0.2.87 dev=eth0 mark=0x200
So the SYN went out fine. The pod’s SYN-ACK came back on eth0 and the kernel dropped it in the input route lookup. Kernel 6.12 reports this as reason 2 (NOT_SPECIFIED). More detailed route-input drop reasons only arrived in 6.13. Turning on martian logging made it explicit:
sysctl -w net.ipv4.conf.all.log_martians=1
dmesg
# IPv4: martian source 10.0.2.87 from 10.0.3.3, on dev eth0
Cause
Here is the chain:
- The SYN-ACK matches Cilium’s
CILIUM_PRE_manglerule-m socket --transparent, which marks it0x200. - Mark
0x200sends it throughip rule fwmark 0x200/0xf00 lookup 2004, and table 2004 is simplylocal default dev lo. This is how TPROXY delivers it to Envoy’s socket. - The kernel then validates the source address. With
net.ipv4.conf.all.src_valid_mark=1, source validation uses the packet’s mark. With mark0x200,10.0.3.3resolves through table 2004 to a local route. - A packet arriving on
eth0whose source looks local is a martian. Dropped. That holds even withrp_filter=0, because a local source is rejected unlessaccept_localis set.
So who set src_valid_mark=1? Not Cilium. The controllers, which don’t run Cilium at all, had it too. The tailscaled journal answers it:
router: enabling connmark-based rp_filter workaround
Tailscale enables this on every start so its own marked traffic passes reverse-path checks. Setting the sysctl back to 0 works until tailscaled restarts, then it comes right back.
Fix
Leave Tailscale’s workaround alone and allow local-looking sources on the node interface:
cat <<'EOF' > /etc/sysctl.d/90-cilium-tailscale.conf
# Cilium TPROXY replies are martian when tailscaled sets all.src_valid_mark=1.
# Replies arrive on eth0 (backend on another node) or a pod lxc* interface
# (backend on the same node), so allow it on all interfaces.
net.ipv4.conf.all.accept_local = 1
net.ipv4.conf.eth0.accept_local = 1
EOF
sysctl -p /etc/sysctl.d/90-cilium-tailscale.conf
To prove it, I killed Envoy’s pooled upstream sockets before each request, so an old connection couldn’t hide the result:
ss -K dst 10.0.3.3 dport = 8080
src_valid_mark | accept_local | Result |
|---|---|---|
| 1 | 0 | timeout |
| 1 | 1 | 200 |
I also added the file to the cloud-init vendor snippet, so new VMs get it from the start:
write_files:
  - path: /etc/sysctl.d/90-cilium-tailscale.conf
    content: |
      net.ipv4.conf.all.accept_local = 1
      net.ipv4.conf.eth0.accept_local = 1
After that, http://192.168.101.152 returned 200 from every Proxmox host and from VMs outside the cluster.
Blockers Along the Way
None of these were the bug, but each one cost time.
My Mac couldn’t reach the LAN. On my laptop, Apple-signed binaries (/usr/bin/ssh, /usr/bin/nc, /usr/bin/curl) reached 192.168.101.0/24, but everything else (k0sctl, kubectl, Homebrew nc) failed with no route to host. Tailscale addresses worked for every binary. I never found the root cause, but I worked around it twice:
k0sctl: a
bastionon each host, pointing at a Proxmox node through its Tailscale address.kubectl: the Tailscale Kubernetes operator with the API server proxy in auth mode (
apiServerProxyConfig.mode: "true"). A tailnet grant maps my identity tosystem:masters, so the kubeconfig has no token at all:{ "src": ["group:admin"], "dst": ["tag:k8s-operator"], "app": { "tailscale.com/cap/kubernetes": [ {"impersonate": {"groups": ["system:masters"]}} ] } }
k0sctl 0.33 waits for nodes to be Ready. With a custom CNI, nodes are never Ready before Cilium is installed, so the first apply timed out and rolled back. Use k0sctl apply --no-wait, then install the CNI.
A Helm release stuck in pending-install. An interrupted cilium install --wait left the release half done. The fix was to delete the release Secret and run helm upgrade --install again. Helm adopts the existing objects because they carry its ownership annotations.
Server-side apply doesn’t prune fields owned by someone else. Helm 4 applies server-side. The first install came from the cilium CLI, which owned some ConfigMap keys (enable-bpf-masquerade, bpf-lb-sock-hostns-only). Removing those options from the values did not remove the keys. I had to recreate cilium-config from Helm once. Watch for this when you move a release between tools.
Envoy keeps its old proxy port after an agent restart. After restarting the Cilium agents, the Gateway’s proxy port moved (14244 to 15016). The standalone cilium-envoy pods lost their xDS stream and never opened the new listener. Requests hung until I restarted them:
kubectl -n kube-system rollout restart ds/cilium-envoy
Lessons
- Let the kernel tell you why it dropped a packet.
kfree_skbwithbpftrace, thenlog_martians, found in minutes what hours of theorizing didn’t. - “It looks like a collision” is a hypothesis, not a finding. The Tailscale mark overlap looked perfect, and it wasn’t the cause.
- Check where a sysctl comes from before you override it.
src_valid_markwasn’t from Debian or Cilium. A daemon reapplied it on every start, so the fix had to be a setting that daemon doesn’t touch. - Asymmetric datapaths and stateful bridges don’t mix. DSR is great on bare metal. Behind a hypervisor firewall that tracks connections, use SNAT.
- Test with fresh connections. Envoy’s connection pool hid the result of a sysctl change once. Kill the pooled sockets before you conclude anything.
Series
This post is part of Homelab Rebuild:
- Part 1: Upgrading Proxmox VE 8 to 9
- Part 2: Starting Over When the IaC Is Broken
- Part 3: When Tailscale Breaks Your Cilium Gateway (this post)
- Part 4: Living on the Tailnet
- Part 5: Secrets Without Secrets in Git
- Part 6: Certificates, DNS and a Private CA
- Part 7: Self-Hosted CI and Getting Back to IaC
- Part 8: Stateful Workloads on Unequal Hardware
- Part 9: Going Public Safely with Cloudflare Tunnel
- Part 10: When the Hypervisor Went Quiet
- Part 11: Hardening the Cluster in Five Layers
- Part 12: Observability with Coroot, and Losing pve-01
- Part 13: The Host That Kept Losing Power
- Part 14: Observability, Take Two with OpenTelemetry
- Part 15: Requests and Limits for Everything
- Part 16: Handing the Cluster to FluxCD
- Part 17: Making the Guardrails Earn Their Keep
- Part 18: When the API Server Outgrew Its VM
- Part 19: Logging In to OpenBao with Cloudflare Access and Google
- Part 20: Headlamp SSO, or Teaching kube-apiserver to Trust Cloudflare Access
- Part 21: pve-02 Loses Power, and Pi-hole Has Nowhere to Go
- Part 22: Turning Four Days of Fixes into AI Runbooks
- Part 23: microVM Sandboxes on Proxmox
- Part 24: Pi-hole Without a Home Host
- Part 25: It Was the Router
- Part 26: TLS on the Front, Plaintext Behind It
- Part 27: One Bad Power Adapter, Two Different Deaths
- Part 28: Observability, Take Three: Making It Worth Looking At
- Part 29: One Meter for Every Model, LiteLLM on Workers AI
- Part 30: Proxmox Joins the SSO, and a Plan Token Loses Admin
- Part 31: First Backups, Postgres, OpenBao and etcd to R2
- Part 32: Alerts That Reach Me, Even When the Lab Is Dead
- Part 33: The Firewall Held, the Tailnet Did Not
- Part 34: From Watching to Blocking, and a Record of Who Did What
- Part 35: Wazuh Without the 8 GB, Endpoint Security for One Mac and Three Hosts
- Part 36: The Fans Were Loud, the CPUs Were Idle
- Part 37: A Power Trip, a Search Domain and a Wildcard
- Part 38: An Autonomous AI Pentester in a Sealed Box
- Part 39: Wasm Pods on k0s, and the Label That Kept Them Packed