Intro
Coroot (Part 12) lasted one day. While pve-01 kept losing power (Part 13), I suspected load. The heaviest thing in the cluster was Coroot: an eBPF agent of about 450 MiB on every node, plus ClickHouse. Load was not the cause, but one question stayed with me. Did I need a service map, or did I need metrics, logs and alerts?
I needed the second. So I replaced Coroot with plain OpenTelemetry: one standard for collection, two small VictoriaMetrics stores, and Grafana on top.
TL;DR: OpenTelemetry Collector (a DaemonSet agent plus a cluster collector) sends everything over OTLP/HTTP to VictoriaMetrics and VictoriaLogs. No Prometheus scraping happens anywhere. Grafana 13 reads both and loads dashboards and alert rules from ConfigMaps. The whole stack uses about 1.9 GiB, against about 3 GiB for Coroot. Two traps: host metrics without a node label, and datasource uid changes in Grafana provisioning.
The Figure
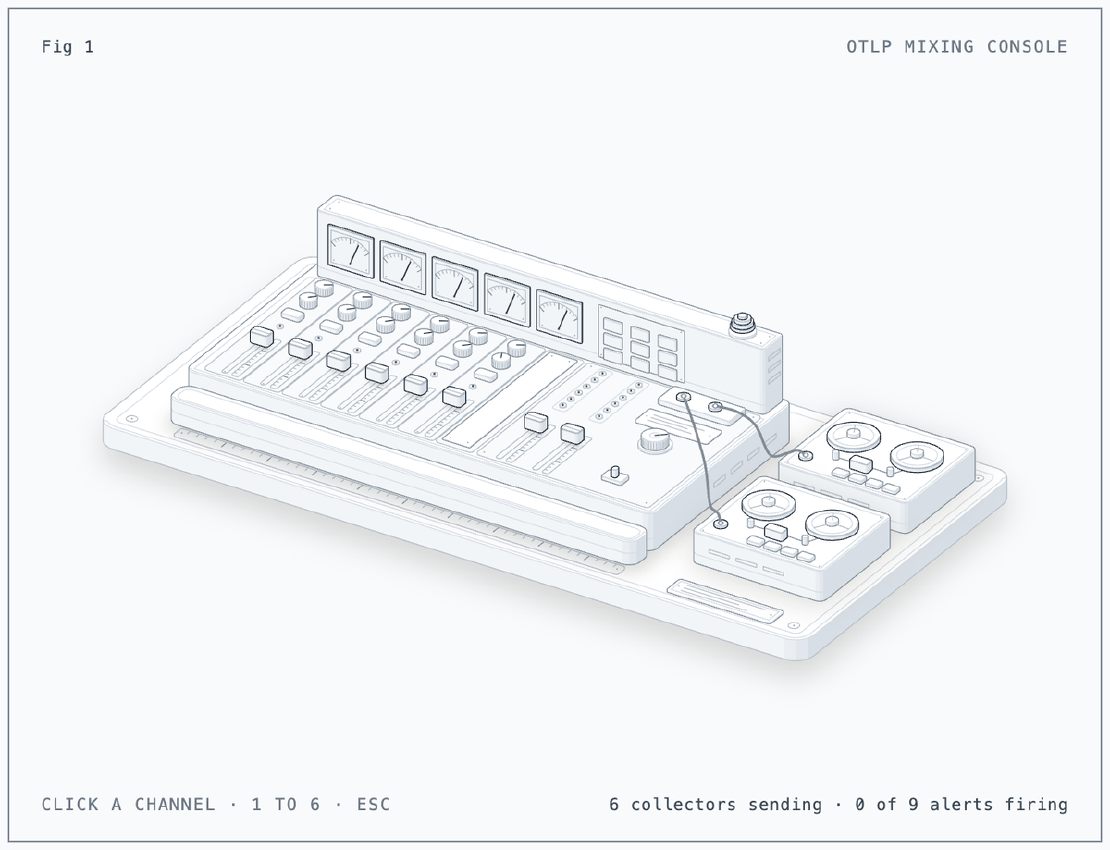
The figure shows the stack as a mixing console. Each channel strip is one collector: five
otel-agent pods, one per worker, and otel-cluster. The patch cords are the
two OTLP/HTTP exporters into the VictoriaMetrics and VictoriaLogs decks. The
meter bridge is the five Grafana dashboards, and the lamp panel is the nine alert
rules. Click a channel or press 1 to 6 to pull it down, and the meters drop.
If an agent stays silent for three minutes (three seconds in the figure),
the Node silent lamp lights and the bell rings for the email. Esc brings
every channel back. I generated the figure with the
anatomy agent skill.
The Situation
- k0s cluster, 5 workers across pve-01, pve-02 and pve-03. The pve-03
worker has the taint
dedicated=quorum:NoSchedule - Two workers have a
local-pathdata disk, labeledlab/data-disk=true - Pod Security
baselineby default and Kyverno policies from Part 11, including one that limits each ExternalSecret tosecret/<namespace>/... - The Proxmox hosts send metrics and logs to Grafana Cloud (free tier) through Grafana Alloy, separately from the cluster
Choosing the Stack
| Need | Pick | Why |
|---|---|---|
| Collection | OpenTelemetry Collector | Vendor-neutral standard. Apps can send OTLP to it later |
| Metrics | VictoriaMetrics single | PromQL, low memory, native OTLP ingestion |
| Logs | VictoriaLogs single | Same family, native OTLP ingestion, LogsQL |
| UI and alerts | Grafana | Already used for Grafana Cloud. One alerting setup |
Both VictoriaMetrics stores accept OTLP directly, so the collector does not need a Prometheus exporter or remote write. Traces have no backend yet. I will add VictoriaTraces when an app sends them.
| Release | Chart | Placement | Storage |
|---|---|---|---|
otel-agent | opentelemetry-collector 0.176.0, DaemonSet | all 5 workers, including pve-03 | none |
otel-cluster | same chart, Deployment, 1 replica | any worker | none |
vmsingle | victoria-metrics-single 0.49.0, 30 days | data-disk workers | 50Gi |
vlogs | victoria-logs-single 0.13.10, 14 days | data-disk workers | 50Gi |
grafana | grafana-community/grafana 13.5.1 | data-disk workers | 1Gi |
The grafana/grafana chart is deprecated. The chart moved to the
grafana-community repo.
Setup
Two collectors
The collector chart has presets (ready-made config blocks) that write most of the config. The agent runs on every node and handles what is local to that node:
mode: daemonset
image:
  repository: otel/opentelemetry-collector-k8s
presets:
  logsCollection:          # /var/log/pods
    enabled: true
  kubeletMetrics:          # pod, container and node metrics
    enabled: true
  hostMetrics:             # CPU, memory, disk, filesystem, network of the VM
    enabled: true
  kubernetesAttributes:    # namespace, pod and workload names on everything
    enabled: true
tolerations:
  - key: dedicated
    operator: Equal
    value: quorum
    effect: NoSchedule
The cluster collector runs as one replica and watches the API server. It uses two presets:
clusterMetrics (node conditions, pod phases, deployment replicas) and
kubernetesEvents (events into the logs store).
Both export over OTLP/HTTP only:
exporters:
  otlphttp/metrics:
    metrics_endpoint: http://vmsingle.monitoring.svc:8428/opentelemetry/v1/metrics
  otlphttp/logs:
    logs_endpoint: http://vlogs.monitoring.svc:9428/insert/opentelemetry/v1/logs
I removed what I do not use: the Jaeger and Zipkin receivers and ports, the
prometheus receiver, and the traces pipeline.
Prometheus names in VictoriaMetrics
OTel metric names look like k8s.pod.cpu.time. With
-opentelemetry.usePrometheusNaming, VictoriaMetrics stores them in the form that
PromQL users expect: k8s_pod_cpu_time_seconds_total, with units and
_total added. One trap: k8s_container_restarts arrives as a gauge, not a
counter, so increase() gives nonsense. Use
max_over_time(...) - min_over_time(...) instead.
Grafana from ConfigMaps
The sidecars of the chart load anything with the label grafana_dashboard or
grafana_alert. So dashboards and alert rules live in Git as files:
kubectl -n monitoring create configmap grafana-dashboard-nodes --from-file=dashboards/nodes.json \
  --dry-run=client -o yaml | kubectl label --local -f - grafana_dashboard=1 -o yaml \
  | kubectl apply --server-side -f -
The admin password and SMTP login come from OpenBao through External Secrets
(secret/monitoring/grafana and secret/monitoring/smtp).
Dashboards and alerts
I made five dashboards, all based on what this cluster actually has:
| Dashboard | Shows |
|---|---|
| Cluster overview | nodes ready, nodes that went silent, pods, restarts, degraded workloads, CPU and memory per node |
| Nodes | per node CPU, load, memory, network, disk I/O, filesystems |
| Workloads | per pod CPU, memory against its limit, containers without a limit, restarts |
| Storage | /mnt/data (where the local-path volumes live) and root disks |
| Logs | log volume and error-like lines per namespace, plus a log viewer |
I also made nine alert rules, sent by email:
| Alert | Fires when |
|---|---|
| Node not ready | the Ready condition is false for 2m |
| Node silent | a known node sends no kubelet data for 3m |
| Node memory high | working set above 85% for 10m |
| Container near memory limit | above 90% of its limit for 10m |
| Container restarting | more than 3 restarts in 15m |
| Deployment, StatefulSet, DaemonSet degraded | ready below desired for 10m |
| Disk filling | / or /mnt/data above 80% for 15m |
“Node silent” exists because “not ready” works only while the API server is up. If the agent on a node stops sending, I can see it even when the cluster is in trouble.
Email goes through Gmail SMTP. Gmail SMTP needs a Gmail App Password, not the account password.
On the first run, “Container near memory limit” already had a match: the Kyverno cleanup controller at 91% of its 128 MiB limit.
Issue 1: Host metrics from all nodes in one line
Symptom
The Nodes dashboard showed one CPU line instead of one line per node. The line jumped between values.
Cause
The hostMetrics preset scrapes the VM itself, and its resource has no
Kubernetes attributes. Without a node label, all five agents wrote the same
series. Each agent overwrote the others.
Fix
Add the node name to everything that the agent sends. The chart already sets
K8S_NODE_NAME from the downward API:
processors:
  resource/node:
    attributes:
      - key: k8s.node.name
        value: ${env:K8S_NODE_NAME}
        action: upsert
service:
  pipelines:
    metrics:
      processors: [memory_limiter, resource/node, batch]
Issue 2: A metric the receiver did not support
Symptom
I enabled k8s.container.status.last_terminated_reason in the cluster
collector to alert on OOM kills. After that, its pod went into CrashLoopBackOff on a config
error.
Cause
The k8s_cluster receiver in collector 0.162.0 does not support that metric.
The collector checks its config at start and refuses to run with an unknown
key.
Fix
Remove it. The “Container near memory limit” alert catches OOM risk before the kill, not after it.
Issue 3: Grafana crashed on a datasource uid
Symptom
I wanted dashboard files to reference datasources, so I added fixed uids (vm,
vlogs) to the provisioned datasources. Grafana crashed on start with
data source not found.
Cause
The datasources already existed in the Grafana database with generated uids. Provisioning matched them by name, then failed to change them to the new uid.
Dead end
My first idea was to delete the rows in the SQLite database by hand. The Grafana image has no shell. During the attempt I deleted the running pod, so Grafana was down for a few minutes for nothing.
Fix
Provisioning can delete datasources before it creates them:
datasources:
  datasources.yaml:
    apiVersion: 1
    deleteDatasources:
      - name: VictoriaMetrics
        orgId: 1
      - name: VictoriaLogs
        orgId: 1
    datasources:
      - name: VictoriaMetrics
        uid: vm
        ...
It runs on every start and does no harm after the uids match.
Issue 4: Small ones
- Dashboards landed in General. The sidecar puts files in the default
folder unless the provider names one:
sidecar.dashboards.provider.folder: Homelab. - Kyverno rejected an ExternalSecret. I applied it without
-n monitoring, so it went todefault. The Kyverno policy from Part 11 lets a namespace read only its own OpenBao path. It refused correctly.
The Proxmox Hosts
The hosts are not Kubernetes nodes, so the OTel stack does not see them. They run Grafana Alloy and send to Grafana Cloud:
- Labels follow the Linux Server integration of Grafana Cloud
(
job="integrations/node_exporter",instance=<hostname>). So its dashboards work, and the three hosts show up separately. - prometheus-pve-exporter runs on pve-02 only. One exporter covers the whole cluster, because the Proxmox API returns every node, guest and storage. Alloy on pve-02 scrapes it.
- Secrets live in
/etc/default/alloyand reach the config throughsys.env. So the config files go into Git as they are.
The free tier has a series limit, and I hit it on the first day. The default
exporter config sent about 7,100 series. I turned off the ZFS collector and
skipped the VM tap interfaces and dm-* devices. I also kept only a few of
the metrics that Alloy reports about itself. That brought it to about 2,500, plus about 670 from the PVE
exporter.
The host down and reboot alerts from Part 13 also live in Grafana Cloud. They must run outside the cluster to catch a host that takes the cluster down.
Result
kubectl -n monitoring exec vmsingle-0 -- wget -qO- http://127.0.0.1:8428/api/v1/series/count
# {"status":"success","data":[8493]}
| Pod | Memory |
|---|---|
otel-agent (each of 5) | about 170 MiB |
otel-cluster | 79 MiB |
vmsingle | 231 MiB |
vlogs | 178 MiB |
grafana (with sidecars) | 583 MiB |
The total is about 1.9 GiB, against about 3 GiB for Coroot with ClickHouse. The biggest difference is per node: 170 MiB for the agent instead of 450 MiB. That difference matters on the 2 GiB pve-03 worker.
Lessons
- Decide what you need before you pick a tool. I wanted metrics, logs and alerts. A service map was nice to have, and it cost the most.
- Prefer the standard for collection. With OTLP, the backends can change without changes to the collectors or the apps.
- Check the labels on host metrics. Metrics from a DaemonSet that carry no node label overwrite each other silently.
- A change to provisioned identifiers needs a migration. For Grafana,
deleteDatasourcesis that migration. - Know your free tier. Default exporters send far more series than a small lab needs. Trim them before the limit does it for you.
- Alerts about the platform belong outside it. The cluster alerts on pods. Grafana Cloud alerts on the hosts.
Series
This post is part of Homelab Rebuild:
- Part 1: Upgrading Proxmox VE 8 to 9
- Part 2: Starting Over When the IaC Is Broken
- Part 3: When Tailscale Breaks Your Cilium Gateway
- Part 4: Living on the Tailnet
- Part 5: Secrets Without Secrets in Git
- Part 6: Certificates, DNS and a Private CA
- Part 7: Self-Hosted CI and Getting Back to IaC
- Part 8: Stateful Workloads on Unequal Hardware
- Part 9: Going Public Safely with Cloudflare Tunnel
- Part 10: When the Hypervisor Went Quiet
- Part 11: Hardening the Cluster in Five Layers
- Part 12: Observability with Coroot, and Losing pve-01
- Part 13: The Host That Kept Losing Power
- Part 14: Observability, Take Two with OpenTelemetry (this post)
- Part 15: Requests and Limits for Everything
- Part 16: Handing the Cluster to FluxCD
- Part 17: Making the Guardrails Earn Their Keep
- Part 18: When the API Server Outgrew Its VM
- Part 19: Logging In to OpenBao with Cloudflare Access and Google
- Part 20: Headlamp SSO, or Teaching kube-apiserver to Trust Cloudflare Access
- Part 21: pve-02 Loses Power, and Pi-hole Has Nowhere to Go
- Part 22: Turning Four Days of Fixes into AI Runbooks
- Part 23: microVM Sandboxes on Proxmox
- Part 24: Pi-hole Without a Home Host
- Part 25: It Was the Router
- Part 26: TLS on the Front, Plaintext Behind It
- Part 27: One Bad Power Adapter, Two Different Deaths
- Part 28: Observability, Take Three: Making It Worth Looking At
- Part 29: One Meter for Every Model, LiteLLM on Workers AI
- Part 30: Proxmox Joins the SSO, and a Plan Token Loses Admin
- Part 31: First Backups, Postgres, OpenBao and etcd to R2
- Part 32: Alerts That Reach Me, Even When the Lab Is Dead
- Part 33: The Firewall Held, the Tailnet Did Not
- Part 34: From Watching to Blocking, and a Record of Who Did What
- Part 35: Wazuh Without the 8 GB, Endpoint Security for One Mac and Three Hosts
- Part 36: The Fans Were Loud, the CPUs Were Idle
- Part 37: A Power Trip, a Search Domain and a Wildcard
- Part 38: An Autonomous AI Pentester in a Sealed Box
- Part 39: Wasm Pods on k0s, and the Label That Kept Them Packed