Intro
Until today, every app got to the cluster by hand: a
helm upgrade per release, or a kubectl apply of a few manifests. The
values were in Git, but nothing made sure that the cluster matched them. Part 15
showed how that goes wrong. One kubectl apply -f on the wrong file created a
second Postgres cluster in default. It ran for three hours before I
noticed.
So I handed the cluster to FluxCD. Git is now the only way a change gets in. This post covers why I chose Flux over Argo CD and how I converted 20 app folders. It also covers how Flux took over the running Helm releases without a reinstall, and the Proxmox cluster split that happened halfway through.
TL;DR: The Flux helm-controller adopts releases installed with the Helm CLI as an ordinary upgrade, so the takeover restarted almost nothing. The Kustomize
helmCharts:block does not work in Flux. Each chart became aHelmRelease, and its values file became a ConfigMap. Every app started suspended, and I switched them on in small batches. During one batch, the three Proxmox hosts lost each other for 22 minutes. The cluster recovered on its own, and one OpenBao pod needed a restart. I still do not know the cause.
The Figure
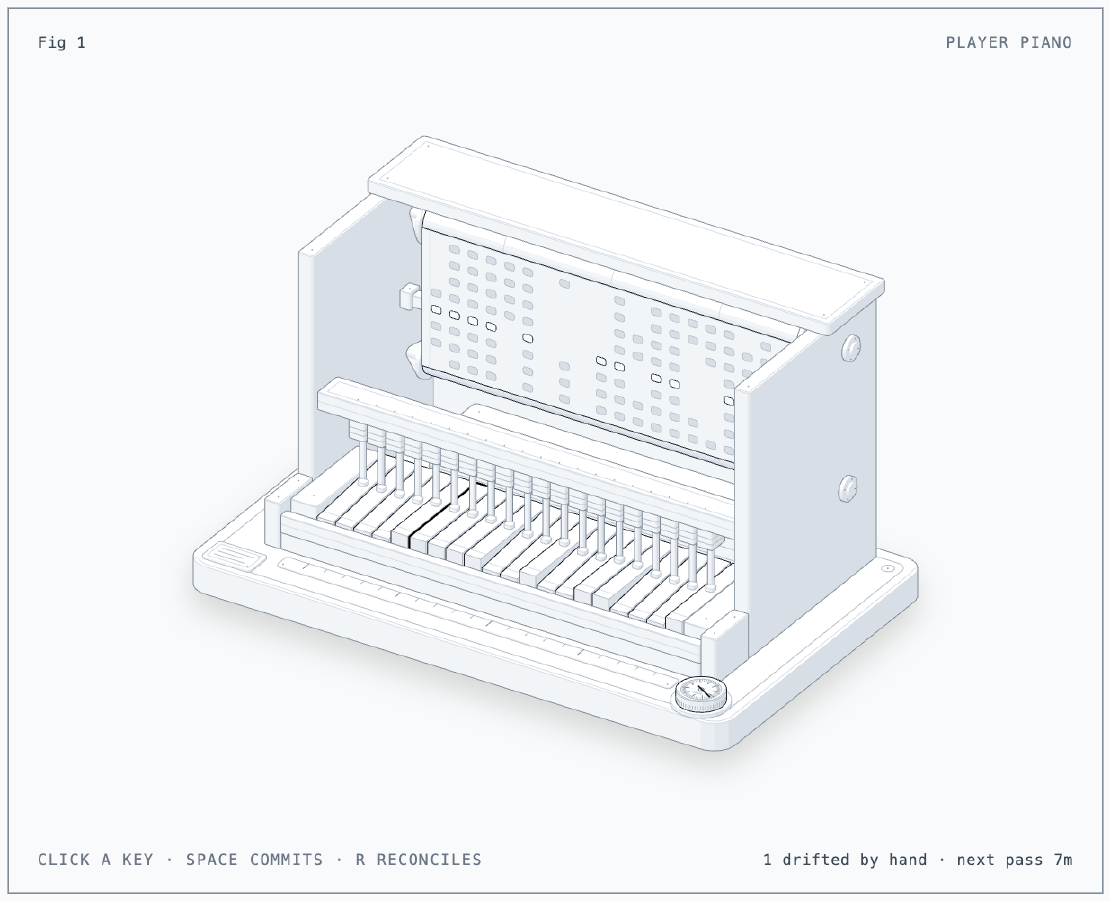
The figure shows Flux as a player piano. The paper roll is the Git repository, with one row
of holes per commit. The 20 keys are the 20 app Kustomizations. Each pass
of the dial on the base is one interval (10 minutes, shown here at a minute
per second). The stack reads the row over the tracker bar. It pushes any key
that differs back to where the roll says. Click a key to change it by hand, as
a kubectl edit does, and watch the next pass put it back. Space pushes a
commit and moves the roll. R is flux reconcile, which applies it without a
wait for the dial. I generated the figure with the
anatomy agent skill.
The Situation
- k0s cluster: three controllers and five workers on three Proxmox hosts (pve-01, pve-02, pve-03)
- 20 app folders under
kubernetes/apps/, 15 of them with a Helm chart - Each app folder had a
kustomization.yamlwith ahelmCharts:block. I used that block only to render locally. The real installs werehelm upgrade --installfrom the README of each app - Some manifests were never in a kustomization at all, and I applied them by hand:
the cert-manager ClusterIssuers, the External Secrets
ClusterSecretStore, Kyverno policies, Grafana dashboards and alert rules - Helm 4.2.1 on my laptop
Flux or Argo CD
| FluxCD | Argo CD | |
|---|---|---|
| Footprint | 3 controllers (source, kustomize, helm), about 250 MiB | Server, repo-server, Redis, application controller, Dex, about 600 MiB to 1 GiB |
| Helm | Real Helm releases through HelmRelease. Adopts existing ones | Renders charts itself. helm list stops reflecting what runs |
| UI | None built in | Good built-in UI |
I am the only person who deploys, memory on these hosts is tight, and everything was already a Helm release. Flux fits. Headlamp already runs in the cluster, and it has a Flux plugin if I want a UI.
Setup
Layout
clusters/homelab/
  flux-system/
    gotk-components.yaml   # flux install --export
    gotk-sync.yaml         # GitRepository + root Kustomization
    kustomization.yaml     # resource patches
  apps.yaml                # one Flux Kustomization per kubernetes/apps/<app>
kubernetes/apps/<app>/     # unchanged place for each app
I installed Flux 2.9.6 with only the three controllers I need: no notification controller, no image automation. The export goes into Git. A kustomize patch sets requests and limits to the policy of the cluster (the Flux defaults are 1 CPU and 1 GiB per controller):
| Controller | Request | Limit |
|---|---|---|
| source-controller, kustomize-controller | 10m / 64Mi | 500m / 256Mi |
| helm-controller | 10m / 128Mi | 500m / 512Mi |
The GitRepository reads the repo over SSH with a read-only deploy key. It
packs only the two folders that Flux needs:
spec:
  url: ssh://git@github.com/<org>/infrastructure
  ref:
    branch: main
  secretRef:
    name: flux-system
  ignore: |
    /*
    !/clusters
    !/kubernetes
One Flux Kustomization per app
apps.yaml has 20 entries like this one:
apiVersion: kustomize.toolkit.fluxcd.io/v1
kind: Kustomization
metadata:
  name: headlamp
  namespace: flux-system
spec:
  suspend: true
  interval: 10m
  retryInterval: 2m
  path: ./kubernetes/apps/headlamp
  prune: true
  wait: false
  sourceRef:
    kind: GitRepository
    name: flux-system
prune: true deletes anything removed from Git. I want that for most
objects, but not for namespaces. If I remove an app folder by mistake, Flux
deletes its namespace, its PVCs and the data on them. Every namespace.yaml
now carries an opt-out:
metadata:
  annotations:
    kustomize.toolkit.fluxcd.io/prune: disabled
helmCharts becomes HelmRelease
The Flux kustomize-controller does not inflate helmCharts:. A short script
turned each block into a chart source and a HelmRelease. It kept the
same release name, namespace and chart version as the live release. So
Flux sees an existing release to upgrade, not a new one to install:
apiVersion: helm.toolkit.fluxcd.io/v2
kind: HelmRelease
metadata:
  name: headlamp
  namespace: headlamp
spec:
  interval: 1h
  releaseName: headlamp
  chart:
    spec:
      chart: headlamp
      version: 0.45.0
      sourceRef:
        kind: HelmRepository
        name: kubernetes-sigs-github-io-headlamp
  valuesFrom:
    - kind: ConfigMap
      name: headlamp-values
      valuesKey: values.yaml
The values files did not move. Kustomize turns each one into a ConfigMap. The watch label tells helm-controller to upgrade as soon as the values change. It does not wait for the next interval:
configMapGenerator:
  - name: headlamp-values
    namespace: headlamp
    files:
      - values.yaml=values.yaml
generatorOptions:
  disableNameSuffixHash: true
  labels:
    reconcile.fluxcd.io/watch: Enabled
Two charts come from OCI registries: Actions Runner Controller, and External
Secrets (its HTTP chart repo timed out in Part 15). Those use an
OCIRepository and chartRef instead.
A few per-app settings carried over lessons from earlier parts:
- Kyverno:
install.disableWaitandupgrade.disableWait. These are the equivalent of the--wait=hookOnlythat got it unstuck in Part 15 - Cilium:
upgrade.disableWait, and no automatic rollback. For the CNI I prefer to fix forward - Tailscale operator: I dropped a
valuesInlineblock that duplicated a key already invalues.yaml
The manifests that I used to apply by hand went into the kustomization of their app.
This includes the Grafana dashboards. They are now ConfigMaps generated with
the grafana_dashboard: "1" label that the sidecar looks for.
A staged takeover
Every Flux Kustomization started with suspend: true, so the merge of the PR
changed nothing in the apps. Then each batch was a one-line commit that flipped
suspend to false. After each commit I checked what restarted:
- headlamp alone, to test adoption
- local-path, LimitRanges, cert-manager, External Secrets, external-dns, gateway, KEDA, the CloudNativePG operator and the Postgres cluster
- monitoring, Pi-hole, cloudflared, Actions Runner Controller, Tailscale operator
- tetragon, Kyverno, OpenBao and Cilium, one at a time
Headlamp answered the main question. The release went from revision 3 (my last
helm upgrade) to revision 4, made by Flux. The pod did not restart:
REVISION  UPDATED                   STATUS      CHART            DESCRIPTION
3         Wed Oct 14 07:38:56 2026  superseded  headlamp-0.45.0  Upgrade complete
4         Wed Oct 14 11:26:27 2026  deployed    headlamp-0.45.0  Upgrade complete
Issue 1: Cluster-scoped objects got a namespace
Symptom
I rendered the Kyverno folder after the conversion:
kind: GeneratingPolicy
metadata:
  name: default-deny-ingress
  namespace: kyverno
Cause
A top-level namespace: in kustomization.yaml sets the namespace on every
object that kustomize does not know as cluster-scoped. It knows built-in kinds
like ClusterRoleBinding, but not custom ones. These are all cluster-scoped custom
resources: the Kyverno policies, the cert-manager ClusterIssuer, the External
Secrets ClusterSecretStore and the Tailscale ProxyClass.
Fix
No top-level namespace: in those four folders. The namespaced objects there
(the generated HelmRelease and ConfigMaps, a Certificate, an
ExternalSecret) set metadata.namespace themselves.
Issue 2: The Flux CLI could not verify TLS
Symptom
failed to get server groups: Get "https://<api-proxy>/api":
tls: failed to verify certificate: SecPolicyCreateSSL error: 0
Cause
I run tools on my laptop inside a sandbox (nono). Go binaries on macOS need access to the system keychain to verify certificates. kubectl worked, but the flux CLI did not.
Fix
I needed the CLI only for flux create secret git. The same
Secret is easy to build by hand. The private key stays in the cluster and in
a temporary folder that I delete right after:
ssh-keygen -q -t ed25519 -N "" -C flux-homelab -f ./identity
ssh-keyscan -t ed25519,ecdsa,rsa github.com > ./known_hosts
kubectl -n flux-system create secret generic flux-system \
  --from-file=identity=./identity \
  --from-file=identity.pub=./identity.pub \
  --from-file=known_hosts=./known_hosts
rm ./identity
gh repo deploy-key add ./identity.pub --repo <org>/infrastructure --title flux-homelab
gh repo deploy-key add creates read-only keys by default. That is all Flux
needs.
One more small thing: the first kubectl apply -k clusters/homelab/flux-system
failed for the GitRepository and Kustomization with
no matches for kind ... ensure CRDs are installed first. The CRDs
from the same apply were not established yet. A second run fixed
it.
Issue 3: The few pods that did restart
Symptom
Most takeovers restarted nothing. A handful of pods rolled once.
Cause
Each one had a different, harmless reason:
| Pods | Why |
|---|---|
| local-path-provisioner | Its Deployment had a kubectl.kubernetes.io/restartedAt annotation from an old kubectl rollout restart. Git does not have it, so Flux removed it. That is a template change |
| External Secrets (3), ARC controller | For OCI charts, Flux adds the digest to the chart version. The helm.sh/chart label went from external-secrets-2.12.0 to external-secrets-2.12.0_4a421e51d491 |
| Kyverno migrate job | The post-upgrade hook of the chart runs on every upgrade |
| cloudflared | Rolled once. I did not check why |
Fix
Nothing to fix. They happen once, on the first Flux upgrade. The two apps I
worried about most were the quietest. OpenBao (revision 7) upgraded with no
field conflict on the webhook caBundle of the injector. In Part 15 that field needed
--server-side=false with the Helm 4 CLI. Cilium
(revision 6) left the agent and Envoy DaemonSets at generation 7, so no node
lost networking.
Issue 4: The hosts lost each other for 22 minutes
Symptom
A few minutes after the batch 3 commit, kubectl through the Tailscale API
proxy started to time out. From the corosync log on pve-01:
11:39:47 corosync[1359]: [TOTEM ] Token has not been received in 2737 ms
11:39:54 corosync[1359]: [TOTEM ] A processor failed, forming new configuration: token timed out (3650ms)
11:40:09 corosync[1359]: [QUORUM] Sync left[2]: 2 3
11:40:09 corosync[1359]: [QUORUM] This node is within the non-primary component and will NOT provide any services.
Each host saw only itself (Nodes: 1, Quorate: No). The links came up
for a few seconds and dropped again, over and over.
Inside the k0s cluster:
- kube-apiserver on controller-03 grew to 2.3 GiB RSS in a 3 GiB VM, with 12 MiB available and no swap
- SSH to controller-01 and controller-02 timed out during the banner exchange
- Controllers that lost their leases restarted: cert-manager, the CloudNativePG operator (10 times), KEDA, Kyverno, cilium-operator (9), the Flux controllers, and one Postgres instance (4)
What it was not
| Suspect | Check | Result |
|---|---|---|
| A host going down | uptime, journalctl --list-boots | All three up the whole time, no reboots |
| Ping failing between hosts | Host firewall rules | A red herring. Between nodes, the Proxmox firewall allows only corosync (UDP 5404-5405) and management ports, so ping always fails |
| Traffic flood | Per-interface rates on pve-01 over 5 seconds | Nothing above 0.2 MiB/s |
| Connection tracking full | nf_conntrack_count | 655 to 1142 of 262144 |
| NIC (Realtek r8169, which stalled once the day before) | ethtool, kernel log | 1 Gbps full duplex, no errors, no link changes |
| The router | Ping from each host to the gateway | Fine throughout. Each host also reached my laptop |
Cause
Unknown. At 12:01:38 all three hosts formed a full membership again on their own, and corosync stayed stable after that. The split started right after the batch 3 commit (monitoring, Pi-hole, cloudflared, ARC, Tailscale operator). But I found nothing that connects those upgrades to host-to-host traffic on the LAN. I leave it as an open question and do not guess. I watch the corosync logs for a repeat.
Fix
Proxmox and k0s recovered by themselves, with two exceptions:
- openbao-2 (the Raft voter on the pve-03 worker) was hung. It wrote no log lines
after 11:51, and its readiness probe (
bao status, 3 second timeout) failed again and again. openbao-0 and openbao-1 kept quorum the whole time. I deleted the pod, and it came back unsealed as a standby. - My laptop lost the Tailscale DNS for
*.ts.net(no such hostfor the API proxy, and nots.netresolver inscutil --dns). A Tailscale reconnect fixed it.
After the split, kube-apiserver was back to 1.4 to 1.8 GiB on all three controllers. The memory spike came from the split, not from Flux.
Update (2026-10-14, later that day): controller-03 ran out of memory again without any split, so the split was not the root cause. The 3 GiB controllers were too small for kube-apiserver. See Part 18.
Result
- 20 apps reconciled from
main. A change is a commit and a push, thenflux reconcile - No more
helm upgradeorkubectl applyby hand. To debug something hands-on, I first suspend the Kustomization of that app - The takeover restarted only the pods in Issue 3. The riskiest releases (OpenBao, Cilium) restarted nothing
- Flux uses about 270 MiB: helm-controller 119 MiB, kustomize-controller 103 MiB, source-controller 49 MiB
Lessons
- Flux adopts Helm CLI releases. Same release name, namespace and chart
version, and the first reconcile is an ordinary
helm upgrade. No reinstall, no downtime. - Start suspended, then switch on in batches. The merge of the GitOps setup changed nothing. Each batch was a one-line commit that I can check or revert.
- Protect namespaces from pruning. One annotation stops a deleted folder from deleting the data under it.
- Kustomize does not know CRD scopes. A top-level
namespace:lands on cluster-scoped custom resources too. - Some restarts on takeover are bookkeeping. Old
restartedAtannotations and OCI digests in chart labels both change the pod template once. - Rule out the obvious before you blame the timing. The split began right after a change I made, and the hosts could not ping each other. But the firewall blocks ping by design, and nothing linked the change to the LAN. Some causes stay open.
Series
This post is part of Homelab Rebuild:
- Part 1: Upgrading Proxmox VE 8 to 9
- Part 2: Starting Over When the IaC Is Broken
- Part 3: When Tailscale Breaks Your Cilium Gateway
- Part 4: Living on the Tailnet
- Part 5: Secrets Without Secrets in Git
- Part 6: Certificates, DNS and a Private CA
- Part 7: Self-Hosted CI and Getting Back to IaC
- Part 8: Stateful Workloads on Unequal Hardware
- Part 9: Going Public Safely with Cloudflare Tunnel
- Part 10: When the Hypervisor Went Quiet
- Part 11: Hardening the Cluster in Five Layers
- Part 12: Observability with Coroot, and Losing pve-01
- Part 13: The Host That Kept Losing Power
- Part 14: Observability, Take Two with OpenTelemetry
- Part 15: Requests and Limits for Everything
- Part 16: Handing the Cluster to FluxCD (this post)
- Part 17: Making the Guardrails Earn Their Keep
- Part 18: When the API Server Outgrew Its VM
- Part 19: Logging In to OpenBao with Cloudflare Access and Google
- Part 20: Headlamp SSO, or Teaching kube-apiserver to Trust Cloudflare Access
- Part 21: pve-02 Loses Power, and Pi-hole Has Nowhere to Go
- Part 22: Turning Four Days of Fixes into AI Runbooks
- Part 23: microVM Sandboxes on Proxmox
- Part 24: Pi-hole Without a Home Host
- Part 25: It Was the Router
- Part 26: TLS on the Front, Plaintext Behind It
- Part 27: One Bad Power Adapter, Two Different Deaths
- Part 28: Observability, Take Three: Making It Worth Looking At
- Part 29: One Meter for Every Model, LiteLLM on Workers AI
- Part 30: Proxmox Joins the SSO, and a Plan Token Loses Admin
- Part 31: First Backups, Postgres, OpenBao and etcd to R2
- Part 32: Alerts That Reach Me, Even When the Lab Is Dead
- Part 33: The Firewall Held, the Tailnet Did Not
- Part 34: From Watching to Blocking, and a Record of Who Did What
- Part 35: Wazuh Without the 8 GB, Endpoint Security for One Mac and Three Hosts
- Part 36: The Fans Were Loud, the CPUs Were Idle
- Part 37: A Power Trip, a Search Domain and a Wildcard
- Part 38: An Autonomous AI Pentester in a Sealed Box
- Part 39: Wasm Pods on k0s, and the Label That Kept Them Packed