Intro
After Part 19, OpenBao got a proper login: Google, through Cloudflare Access,
with short-lived tokens. Headlamp, my Kubernetes UI, still wanted a pasted
ServiceAccount token from kubectl create token. I wanted the same Google
login there.
It looks like the same job, but it is not. OpenBao checks the ID token itself. Headlamp does not. It forwards your token to the Kubernetes API server, so kube-apiserver is the one that must trust Cloudflare Access.
TL;DR: I added a second Cloudflare Access SaaS app (OIDC) for Headlamp. A structured
AuthenticationConfigurationon kube-apiserver trusts that app’s tokens and maps my email to useroidc:<email>. A ClusterRoleBinding gives that user its rights. The API server change went out to the three k0s controllers one at a time, with checks on etcd, leases and the controller count in between. SSO works. The token login is still there for when Cloudflare or Google is down.
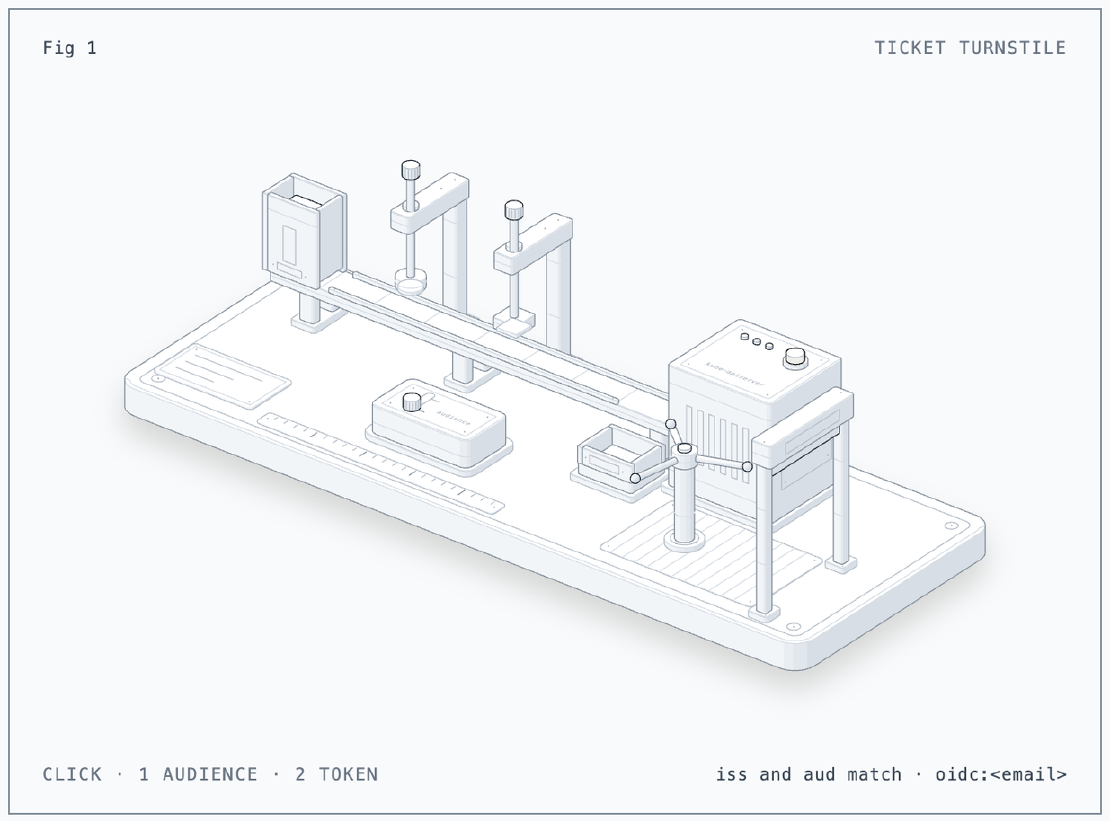
The Figure
A pass leaves the hopper on the left, gets a round stamp from Google and a
square seal from the Cloudflare Access embosser, then slides into the
kube-apiserver cabinet. The audience switch in front selects which Access app
seals it. A Headlamp pass matches, so the lamp lights, the rotor turns and the
shutter on Headlamp’s door lifts. A pass sealed by the OpenBao app comes back
into the tray. Click the left half or press 1 to flip the audience. Click the
right half or press 2 to send a ServiceAccount token through Use A Token.
I generated the figure with the anatomy agent skill. It builds interactive isometric SVG figures from a description of the system.
The Situation
- k0s v1.36.4 with three controllers. kube-apiserver runs as a host process
managed by k0s, not as a static pod, and its flags come from the k0s
ClusterConfig(spec.api.extraArgs) - Headlamp 0.45.0 (chart 0.45.0), reachable on the tailnet at
https://headlamp.<tailnet>.ts.net, plus a LAN hostname - Login before: a short-lived token for the
headlamp-adminServiceAccount, bound tocluster-admin - Cloudflare Access already set up with Google as an identity provider (Part 19)
Setup
How the token flows
browser -> Headlamp -> Cloudflare Access (OIDC app "Headlamp") -> Google
browser <- Headlamp <- ID token (aud = Headlamp client ID, email = me)
Headlamp -> kube-apiserver: Authorization: Bearer <ID token>
kube-apiserver: issuer and audience match? -> user oidc:<email> -> RBAC
I created a second SaaS app in Cloudflare Access instead of reusing
OpenBao’s. Each app has its own client ID, and that ID becomes the token’s
audience. So a token issued for OpenBao cannot be replayed against the API server. The
app has one redirect URL, https://headlamp.<tailnet>.ts.net/oidc-callback,
because Headlamp accepts a single callback URL. SSO therefore works on the
tailnet hostname, which reaches it from anywhere anyway.
kube-apiserver: structured authentication
Kubernetes now has a configuration file for this (--authentication-config),
instead of the old --oidc-* flags:
apiVersion: apiserver.config.k8s.io/v1
kind: AuthenticationConfiguration
jwt:
  - issuer:
      url: https://<team>.cloudflareaccess.com/cdn-cgi/access/sso/oidc/<client-id>
      audiences:
        - <client-id>
    claimMappings:
      username:
        claim: email
        prefix: "oidc:"
The oidc: prefix keeps these users apart from anything else named after an
email address. Certificates and ServiceAccount tokens do not change. This
only adds a trusted issuer.
In the repo, k0sctl.yaml gets the flag and uploads the file to the three
controllers:
spec:
  k0s:
    config:
      spec:
        api:
          extraArgs:
            authentication-config: /etc/k0s/authentication-config.yaml
  hosts:
    - role: controller
      files:
        - name: apiserver-authentication-config
          src: k0s/authentication-config.yaml
          dstDir: /etc/k0s
          perm: "0644"
RBAC
The user name the API server sees is oidc:<my email>. One binding gives it
the same rights the old token had:
apiVersion: rbac.authorization.k8s.io/v1
kind: ClusterRoleBinding
metadata:
  name: headlamp-oidc-admin
roleRef:
  apiGroup: rbac.authorization.k8s.io
  kind: ClusterRole
  name: cluster-admin
subjects:
  - apiGroup: rbac.authorization.k8s.io
    kind: User
    name: oidc:<my email>
Two parts of this needed an explicit yes from me: giving a new identity
cluster-admin, and changing how the API server authenticates. The change
was ready and staged. It went out only after I approved it.
Headlamp: settings from OpenBao
The chart can read its OIDC settings from an existing Secret. The client ID,
secret, issuer and callback URL went into OpenBao at secret/headlamp/oidc.
The client secret went from the clipboard into stdin and was never printed.
An ExternalSecret renders the keys Headlamp expects:
target:
  name: headlamp-oidc
  template:
    data:
      OIDC_CLIENT_ID: "{{ .client_id }}"
      OIDC_CLIENT_SECRET: "{{ .client_secret }}"
      OIDC_ISSUER_URL: "{{ .issuer }}"
      OIDC_SCOPES: "openid,email,profile"
      OIDC_CALLBACK_URL: "{{ .callback_url }}"
One chart quirk: with an external secret, the chart passes
-oidc-callback-url only if config.oidc.callbackURL is non-empty in the
values. The actual value still comes from the Secret. So the values hold a
dummy string only to switch the flag on.
Rolling it out without losing the API
kube-apiserver reads --authentication-config only at start, so k0s on each
controller needs a restart. There are three controllers with etcd on each.
If I restart them together, the API goes down. If I restart them one at a
time, the API stays up. Per controller:
- Write
/etc/k0s/authentication-config.yaml. - Back up
/etc/k0s/k0s.yaml, then add theextraArgsentry underapi:. systemctl restart k0scontroller.- Check that kube-apiserver runs with the flag and answers:
--authentication-config=/etc/k0s/authentication-config.yaml
apiserver http 401
401 is the healthy answer here. Anonymous access is off, so a running
server refuses an unauthenticated /readyz.
- Before you go to the next controller, make sure that k0s counts three controllers again, etcd is healthy, and all controller leases are fresh:
count=3
[+]etcd ok
[+]etcd-readiness ok
Controller-01 at 04:42 UTC, controller-02 at 04:43, controller-03 at 04:44. The rollback for each one was a single command: restore the backup and restart.
Issue 1: A host went down during the rollout
Symptom
The write of the Headlamp settings into OpenBao failed before it wrote anything:
error: unable to upgrade connection: error dialing backend:
dial tcp 192.168.101.51:10250: connect: no route to host
Cause
That address is a worker on pve-02, and pve-02 lost power. That is Part 21.
Fix
Wait. The API server change needs all three controllers healthy, and controller-02 lives on pve-02. When pve-02 was back and controller-02 renewed its lease, the rollout continued.
Result
The Headlamp login page now has Sign In (Cloudflare Access, then Google) and Use A Token side by side. Signing in lands in Headlamp as me, with the Flux view from Part 17.
Break-glass is intact on three levels:
| If this fails | Still works |
|---|---|
| Cloudflare or Google | Headlamp’s Use A Token with a headlamp-admin ServiceAccount token (checked: the API server still returns 200 for one) |
| Headlamp | kubectl through the Tailscale API proxy |
| Tailscale | kubectl on the LAN to the API VIP with the admin client certificate |
Update (2026-10-16): SSO only works on the Tailscale address. The OIDC callback URL is that one name. A login started on the LAN name (
kubernetes.franzramadhan.lab) finishes in a popup on a different origin. That popup cannot hand the session back. The popup sits on “Redirecting to main page…” forever. On the LAN name I use Use A Token.
Update 2026-10-21: Logged out too early
Headlamp kept signing me out after a few minutes, while OpenBao, Proxmox and LiteLLM stayed signed in. The pod logs said why, about once a minute:
refreshing token: oauth2: token expired and refresh token is not set
Headlamp forwards the ID token to kube-apiserver on every request, so the session lasts exactly as long as that token. The other apps use the token once at login and then keep their own session. A short token never caused them a problem. Cloudflare’s ID token lives for only a few minutes, and Headlamp had no refresh token to renew it with.
My first try was in the Cloudflare SaaS app: Access token lifetime 1h and
refresh tokens on. I signed in again and was logged out seven minutes later,
with the same error. The lifetime setting did not help, because Headlamp checks
the ID token’s exp, not the access token’s. And there was still no refresh
token, because Headlamp never asked for one. In OIDC, a client that wants a
refresh token requests the offline_access scope. My scopes were only
openid,email,profile.
The fix was one word on the Headlamp side:
OIDC_SCOPES: "openid,email,profile,offline_access"
Headlamp reads the scopes only at startup, so the pod needed a restart. I also signed in again to get a session with a refresh token. Since then, Headlamp renews the token in the background. The log went from one error every few seconds to none. RBAC and the API server configuration did not change.
Lessons
- Know who validates the token. OpenBao validates OIDC tokens itself. Headlamp passes them on, so the API server must trust the issuer.
- One app per audience. A separate Cloudflare Access app gives Headlamp’s tokens their own audience, so they cannot be used anywhere else.
- Structured authentication beats
--oidc-*flags. One file, versioned in the repo, with room for more issuers later. - Restart quorum members one at a time and check between. The controller count, etcd health and leases told me when it was safe to touch the next one.
- Changes that grant power deserve an explicit yes. I staged everything and approved the last step separately. It cost a few minutes and nothing else.
- Keep a way in that does not depend on the new way in. SSO is the daily path. The token, Tailscale and the LAN certificate are the fallbacks.
Series
This post is part of Homelab Rebuild:
- Part 1: Upgrading Proxmox VE 8 to 9
- Part 2: Starting Over When the IaC Is Broken
- Part 3: When Tailscale Breaks Your Cilium Gateway
- Part 4: Living on the Tailnet
- Part 5: Secrets Without Secrets in Git
- Part 6: Certificates, DNS and a Private CA
- Part 7: Self-Hosted CI and Getting Back to IaC
- Part 8: Stateful Workloads on Unequal Hardware
- Part 9: Going Public Safely with Cloudflare Tunnel
- Part 10: When the Hypervisor Went Quiet
- Part 11: Hardening the Cluster in Five Layers
- Part 12: Observability with Coroot, and Losing pve-01
- Part 13: The Host That Kept Losing Power
- Part 14: Observability, Take Two with OpenTelemetry
- Part 15: Requests and Limits for Everything
- Part 16: Handing the Cluster to FluxCD
- Part 17: Making the Guardrails Earn Their Keep
- Part 18: When the API Server Outgrew Its VM
- Part 19: Logging In to OpenBao with Cloudflare Access and Google
- Part 20: Headlamp SSO, or Teaching kube-apiserver to Trust Cloudflare Access (this post)
- Part 21: pve-02 Loses Power, and Pi-hole Has Nowhere to Go
- Part 22: Turning Four Days of Fixes into AI Runbooks
- Part 23: microVM Sandboxes on Proxmox
- Part 24: Pi-hole Without a Home Host
- Part 25: It Was the Router
- Part 26: TLS on the Front, Plaintext Behind It
- Part 27: One Bad Power Adapter, Two Different Deaths
- Part 28: Observability, Take Three: Making It Worth Looking At
- Part 29: One Meter for Every Model, LiteLLM on Workers AI
- Part 30: Proxmox Joins the SSO, and a Plan Token Loses Admin
- Part 31: First Backups, Postgres, OpenBao and etcd to R2
- Part 32: Alerts That Reach Me, Even When the Lab Is Dead
- Part 33: The Firewall Held, the Tailnet Did Not
- Part 34: From Watching to Blocking, and a Record of Who Did What
- Part 35: Wazuh Without the 8 GB, Endpoint Security for One Mac and Three Hosts
- Part 36: The Fans Were Loud, the CPUs Were Idle
- Part 37: A Power Trip, a Search Domain and a Wildcard
- Part 38: An Autonomous AI Pentester in a Sealed Box
- Part 39: Wasm Pods on k0s, and the Label That Kept Them Packed