Intro
In Part 21 pve-02 lost power, and
Pi-hole went down with it. Its settings sat on a local-path volume on
k0s-pve-02-worker-1, so the pod could run only there. pve-02 dropped four
more times the next day, and each time the LAN lost DNS.
I wanted Pi-hole to survive the loss of any one host. My first idea was to move its state to the Postgres cluster, which already fails over between hosts. Pi-hole cannot do that (it speaks only SQLite), but it turned out that it did not need to.
TL;DR: Pi-hole had almost no state worth keeping. Everything that matters (local DNS, upstreams, the blocklist) now lives in Helm values. So I run two replicas without a volume, one per Proxmox host. The upgrade failed first, because a field owned by the old Helm CLI survived server-side apply. One upgrade with
serverSideApply: disabledfixed that. Then both pods landed on one host, until I addedmatchLabelKeys: [pod-template-hash]to the spread rule. When I deleted the pod that held the DNS IP, the test lost 0 of 40 queries.
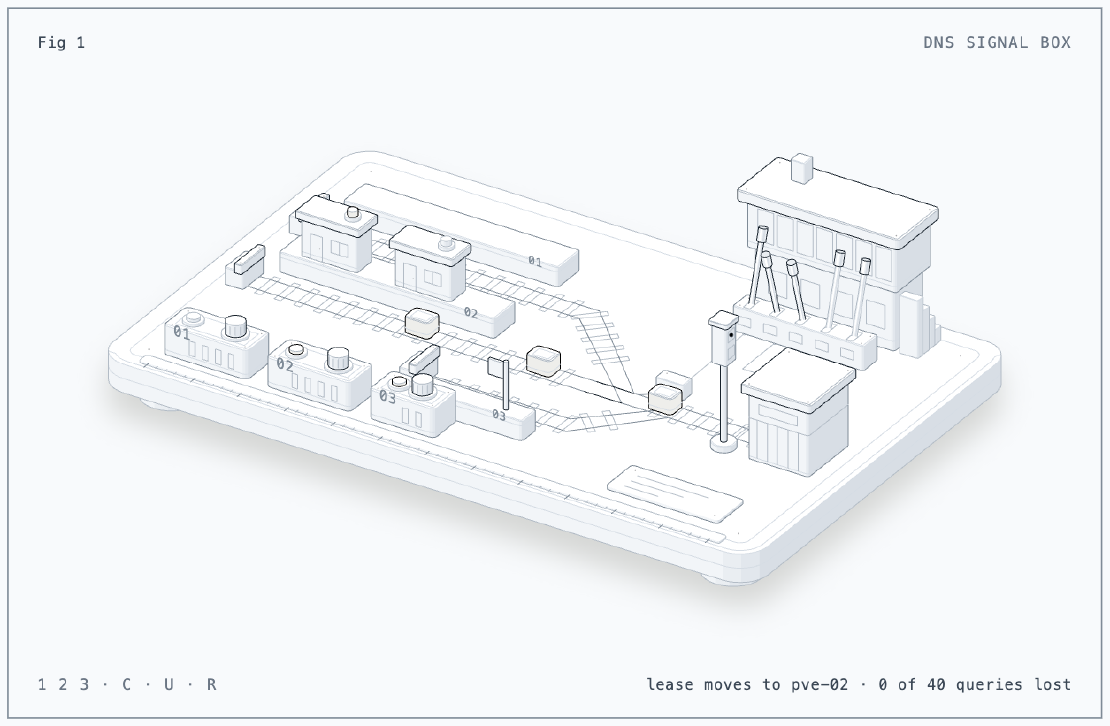
The Figure
The figure is a model railway. Each wagon is a DNS query to 192.168.101.161.
The points send it to the platform of the host whose node holds the L2
lease (the Cilium record of which node announces the IP). Huts are Pi-hole pods, and the goods shed on platform 02 is the old
local-path volume. Press 1, 2 or 3 to cut or restore a host’s power.
Before the change, a cut to pve-02 closes the line. Lever 3 is the upgrade to
two stateless replicas. U tries it, but the clamp (the field the old Helm CLI
still owns) holds it until C takes the clamp off. After the upgrade, a cut to
the lease holder moves the lease and the points. R runs a rollout that
spreads the pods again. I generated it with the
anatomy agent skill.
The Situation
- Pi-hole 2026.07.2, chart
pihole2.38.0, managed by Flux (helm-controller v1.6.5). - One replica, 1 GiB
local-pathPVC, pinned to the data-disk workers. - LAN DNS on
192.168.101.161, a LoadBalancer IP announced by Cilium L2 withexternalTrafficPolicy: Local, so the query log shows real client IPs. - The same pods also serve the tailnet through a Tailscale LoadBalancer.
- Workers: two on pve-01, two on pve-02, one on pve-03. The pve-03 worker is
tainted for quorum only. Nodes carry
topology.kubernetes.io/zoneset to their host.
What was actually on the volume
Before I decided anything, I looked at what Pi-hole stored:
kubectl -n pihole exec deploy/pihole -- pihole-FTL sqlite3 /etc/pihole/gravity.db \
  "select address from adlist; select count(*) from domainlist;"
# https://raw.githubusercontent.com/StevenBlack/hosts/master/hosts
# 0
There was one default blocklist and no allow or deny entries. The *.franzramadhan.lab
wildcard and the Proxmox host names were already in the Helm values as
dnsmasq lines. The only thing the volume really held was the query log
and its stats.
So the fix was not “make the state highly available”. It was “stop having state”: put the blocklist in values too, drop the volume, and run two copies.
replicaCount: 2

topologySpreadConstraints:
  - maxSkew: 1
    topologyKey: topology.kubernetes.io/zone
    whenUnsatisfiable: DoNotSchedule
    nodeTaintsPolicy: Honor
    labelSelector:
      matchLabels:
        app: pihole
        release: pihole

podDisruptionBudget:
  enabled: true
  minAvailable: 1

adlists:
  - https://raw.githubusercontent.com/StevenBlack/hosts/master/hosts

persistentVolumeClaim:
  enabled: false
nodeTaintsPolicy: Honor leaves tainted nodes out of the spread. That
keeps the quorum-only pve-03 worker out. It also lets both pods share a host
while the other host is down.
Issue 1: The upgrade rejected its own Deployment
Symptom
Flux applied the change and the HelmRelease failed:
Helm upgrade failed for release pihole/pihole with chart pihole@2.38.0:
server-side apply failed for object pihole/pihole apps/v1, Kind=Deployment:
Deployment.apps "pihole" is invalid:
[spec.template.spec.volumes[0].persistentVolumeClaim: Forbidden: may not specify more than 1 volume type,
 spec.template.spec.containers[0].volumeMounts[0].name: Not found: "config"]
The old pod kept running, so DNS stayed up.
Cause
The new chart output had volume config as emptyDir: {}. The live
Deployment had config as persistentVolumeClaim. Server-side apply merged
the two into one volume with both sources, and the API refused it.
It did not remove the old field, because Flux did not fully own the old field. The managed fields showed two owners:
helm             Apply   persistentVolumeClaim
helm-controller  Apply   persistentVolumeClaim
I installed Pi-hole with the Helm CLI before Flux took over
(Part 16). That install is the
helm manager, and it still owned the field. Server-side apply
removes a field only when no other manager owns it. So it was not enough
for helm-controller to drop it from its own config.
Dead end: upgrade.force
The usual advice is force: true. The field description says why that
has no effect here:
Force forces resource updates through a replacement strategy
that avoids 3-way merge conflicts on client-side apply.
This field is ignored for server-side apply
Fix
One upgrade with client-side apply:
spec:
  upgrade:
    serverSideApply: disabled
A client-side 3-way merge compares the previous release (which had the PVC) with the new one (which does not). Then it sends a patch that deletes the PVC source. The upgrade went through, and Helm removed the old PVC itself. I took the setting out again in the next change.
Issue 2: Both pods on the same host
Symptom
pihole-6d65594f98-6spz4   1/1   Running   k0s-pve-01-worker-1
pihole-6d65594f98-t486s   1/1   Running   k0s-pve-01-worker-1
Two replicas, one node, one host. The spread rule exists to prevent exactly this.
Cause
During the rolling update, the old pod was still running on pve-02. It has
the same app and release labels, so the scheduler counted it. pve-02
already had one Pi-hole and pve-01 had none. So both new pods went to pve-01
without breaking maxSkew: 1. Then Kubernetes removed the old pod.
Fix
Count only pods from the same ReplicaSet:
    matchLabelKeys:
      - pod-template-hash
The next rollout put one pod on each host:
pihole-796b7b55c4-8hxws   1/1   Running   k0s-pve-02-worker-1
pihole-796b7b55c4-clwf2   1/1   Running   k0s-pve-01-worker-1
Failover test
Cilium announces 192.168.101.161 from one node with a local Pi-hole pod
(the holder of the cilium-l2announce-pihole-pihole-dns lease). I deleted
the pod on the holder while pve-03 queried the IP once per second:
for i in $(seq 1 40); do
  dig +short +time=1 +tries=1 @192.168.101.161 example.com | head -1
  sleep 1
done
| Value | |
|---|---|
| Lease holder before | k0s-pve-01-worker-1 |
| Lease holder after | k0s-pve-02-worker-1 |
| Failed queries | 0 of 40 |
| Replacement pod | k0s-pve-01-worker-2 |
Result
- LAN DNS on the same IP, now served from both hosts.
- No volume, so nothing ties Pi-hole to a node anymore.
- A PodDisruptionBudget keeps one replica up during drains.
- Trade-off: each replica has its own query log and stats, and a restart loses both. The web UI shows one replica per page load.
Update 2026-10-17: two releases, not two replicas
A day later the web UI broke. The login looped with “too many redirects”,
and buttons needed two clicks. DNS itself was fine (40 of 40 queries on
.161, 30 of 30 on the tailnet).
Cause. Pi-hole v6 keeps login sessions in memory, per pod. With two
replicas behind lab-gateway, each request can land on either pod. One
session made ten dashboard API calls:
401 401 200 401 200 200 401 200 200 401
Sticky sessions (each client always goes to the same pod) can fix it, but
Cilium’s Gateway Envoy has none. It ignores the Service’s
sessionAffinity: ClientIP. I tested it live, and the result was still a mix of
200 and 302. Its lb-l7-algorithm annotation offers only round_robin,
least_request and random. The Gateway API CRDs here are the standard
channel, without sessionPersistence.
Fix. Two Helm releases with one pod each instead of one release with two replicas, named by the host they belong to:
| Release | Prefers | Serves |
|---|---|---|
pihole-1 | pve-01 (zone affinity) | DNS and the web UI |
pihole-2 | pve-02 (zone affinity) | DNS |
The LAN DNS address .161 moved to a hand-written Service that selects
app: pihole, so it belongs to neither release and answers from both. The
move took two steps (add the new releases, then remove the old ones). During
the switch, a DNS probe every half second got answers to 600 of 600 queries.
After the switch, one session made ten API calls, and all returned 200.
When I picked the host by name, that also fixed the placement. My first two attempts used pod anti-affinity, and both put the two new pods on one host. Old pods were still running on both hosts during the rollout, so neither host looked better.
Lessons
- Check what the state is before you make it highly available. I was ready to fight Pi-hole into Postgres. A two-line SQL check showed there was nothing to move.
- Helm CLI history lives on in managed fields. Flux adopted the
release, but the
helmfield manager stayed. The removal of a value can fail months later on a field that Flux never fully owned. upgrade.forceis a client-side apply option. Under server-side apply it is ignored.serverSideApply: disabledfor one upgrade is the switch that matters.- Topology spread counts every matching pod, old ones too. Without
matchLabelKeys: [pod-template-hash], a rolling update can stack the new pods away from the old one. - Test failover by removing the thing that holds the IP. Deleting a random pod proves little. Deleting the one behind the L2 lease proves that the IP moves.
Series
This post is part of Homelab Rebuild:
- Part 1: Upgrading Proxmox VE 8 to 9
- Part 2: Starting Over When the IaC Is Broken
- Part 3: When Tailscale Breaks Your Cilium Gateway
- Part 4: Living on the Tailnet
- Part 5: Secrets Without Secrets in Git
- Part 6: Certificates, DNS and a Private CA
- Part 7: Self-Hosted CI and Getting Back to IaC
- Part 8: Stateful Workloads on Unequal Hardware
- Part 9: Going Public Safely with Cloudflare Tunnel
- Part 10: When the Hypervisor Went Quiet
- Part 11: Hardening the Cluster in Five Layers
- Part 12: Observability with Coroot, and Losing pve-01
- Part 13: The Host That Kept Losing Power
- Part 14: Observability, Take Two with OpenTelemetry
- Part 15: Requests and Limits for Everything
- Part 16: Handing the Cluster to FluxCD
- Part 17: Making the Guardrails Earn Their Keep
- Part 18: When the API Server Outgrew Its VM
- Part 19: Logging In to OpenBao with Cloudflare Access and Google
- Part 20: Headlamp SSO, or Teaching kube-apiserver to Trust Cloudflare Access
- Part 21: pve-02 Loses Power, and Pi-hole Has Nowhere to Go
- Part 22: Turning Four Days of Fixes into AI Runbooks
- Part 23: microVM Sandboxes on Proxmox
- Part 24: Pi-hole Without a Home Host
- Part 25: It Was the Router
- Part 26: TLS on the Front, Plaintext Behind It
- Part 27: One Bad Power Adapter, Two Different Deaths
- Part 28: Observability, Take Three: Making It Worth Looking At
- Part 29: One Meter for Every Model, LiteLLM on Workers AI
- Part 30: Proxmox Joins the SSO, and a Plan Token Loses Admin
- Part 31: First Backups, Postgres, OpenBao and etcd to R2
- Part 32: Alerts That Reach Me, Even When the Lab Is Dead
- Part 33: The Firewall Held, the Tailnet Did Not
- Part 34: From Watching to Blocking, and a Record of Who Did What
- Part 35: Wazuh Without the 8 GB, Endpoint Security for One Mac and Three Hosts
- Part 36: The Fans Were Loud, the CPUs Were Idle
- Part 37: A Power Trip, a Search Domain and a Wildcard
- Part 38: An Autonomous AI Pentester in a Sealed Box
- Part 39: Wasm Pods on k0s, and the Label That Kept Them Packed